I read Empires of AI, by Niall Ferguson, Lisa Klaassen and Eric Schmidt, and kept thinking about what happens if the people winning the race stop running.
Their argument is serious. The United States and China control much of the capital, computing infrastructure and model development on which the rest of us increasingly depend. Those dependencies give them power. A supplier can change its prices. A government can restrict access. You cannot run a country on the assumption that neither will happen. [1]
The authors also warn that the cost of the race could exhaust its leaders. On that, I agree. Staying ahead means more research, more computing capacity, access to chips and electricity, and another model sufficiently better to justify what it cost.
My disagreement begins with what that means for everyone outside those laboratories. If your lead has to be bought again and again, I want to know how much of it becomes lasting power, and how much becomes cheaper capability for everyone else.
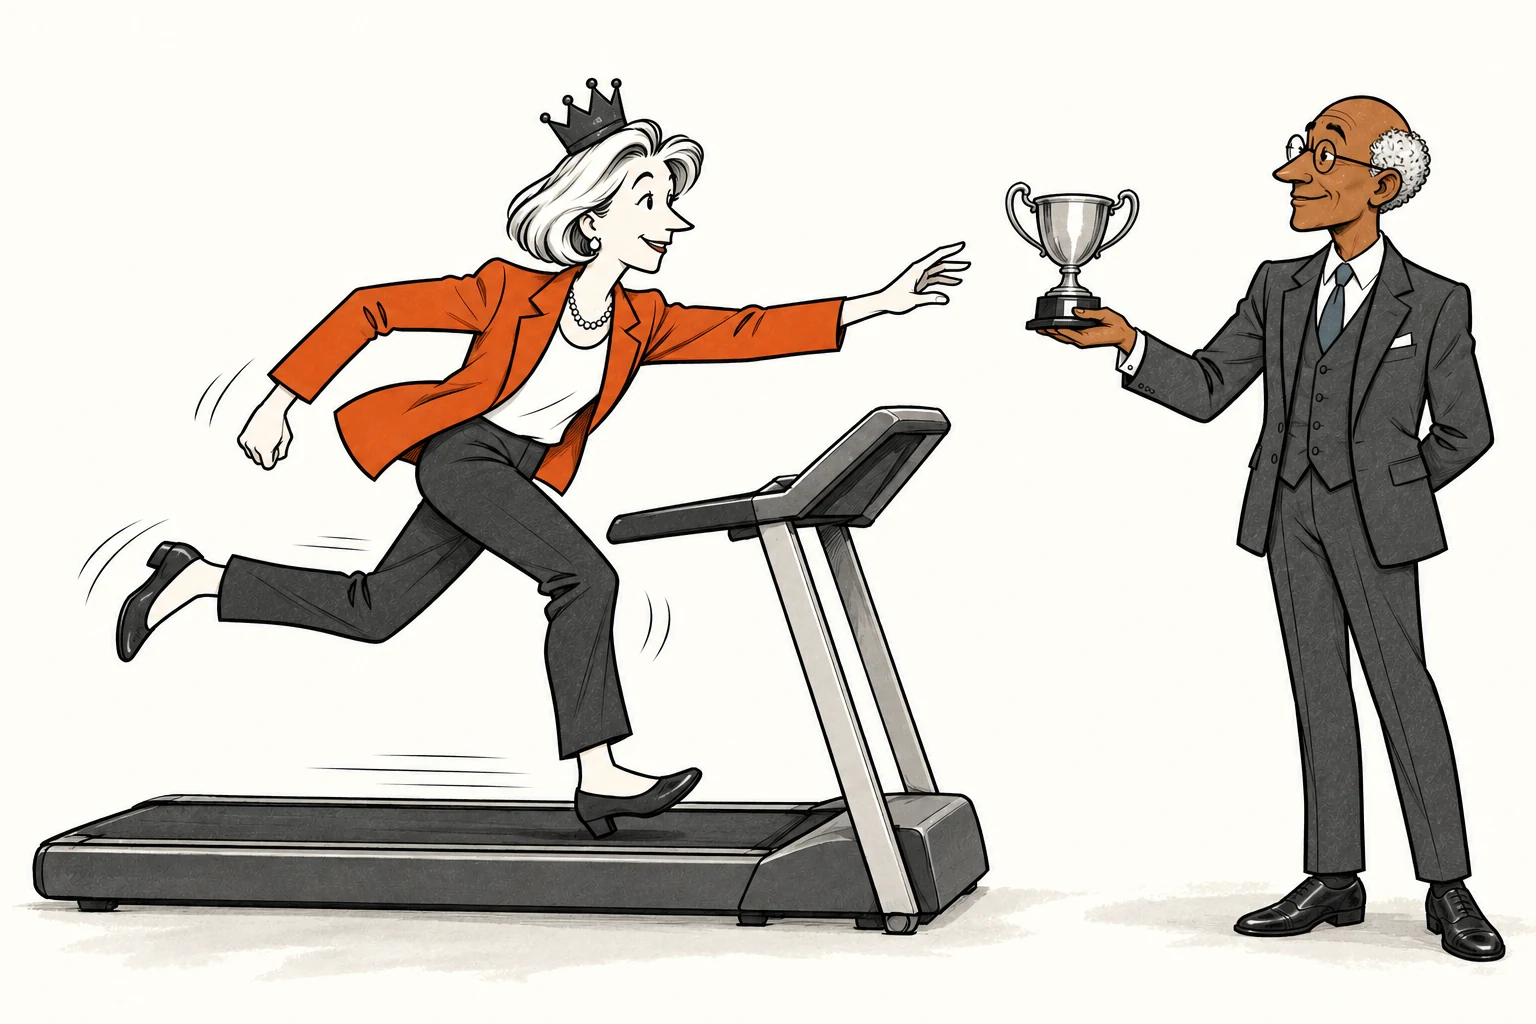
A lead that has to be renewed
There is evidence behind the feeling that the others are catching up almost as soon as a breakthrough arrives.
Epoch AI estimated that, on its broad capability index, the best open-weight models in early 2026 were roughly four months behind the frontier on average. Use a stricter definition of catching up, and the estimate becomes six months. That is a measurement over a particular period, not a promise that every new model will have an equivalent freely available six months later. [2]
The gap can widen, too. Stanford’s 2026 AI Index records the open–closed performance gap reopening after it had narrowed. Some capabilities are harder to reproduce; some models are not widely available; a benchmark result is not the same thing as a dependable product. [3]
Even with those qualifications, the economic pressure is clear. A laboratory cannot assume that today’s exceptional capability will remain exceptional at today’s price.
Its access to money, talent and infrastructure may let it win several races in a row. That is a real advantage. Maintaining it still requires work and expenditure. I would be careful about treating a lead that needs constant renewal as ownership of everyone else’s future.
And this is not a tidy division between America producing closed models and China producing open ones. There are exceptions on both sides. By open weights, I mean that the trained model can be downloaded; licences and permissions still vary. A model’s nationality does not tell you everything you need to know about the terms on which you can use it.
Training the model, then putting it to work
I think we need to separate two things that get bundled together in this debate.
Training develops the model’s capabilities. Inference is running a trained model to produce an answer, prediction or action. When someone asks AI to explain a difficult passage or help fix a piece of code, they are using inference.
The same company can do both. The same infrastructure can support both. But the economics facing someone developing the next frontier model are different from those facing someone using an existing model to solve a customer’s problem.
The second person does not have to finance the original training programme. They can pay to use a model through an API, or operate an available model themselves. The API price can help fund the supplier’s research, of course. The user is buying a service rather than taking on the entire research commitment.
That distinction matters because useful capability can become cheaper while the frontier remains expensive. Stanford recorded a more than 280-fold fall in the inference price of models reaching a particular GPT-3.5 benchmark level between November 2022 and October 2024. This was a comparison at a fixed capability threshold, not a claim that all AI work became 280 times cheaper. [4]
For someone building a useful service, an improvement that is no longer exclusive may be exactly what they need. They do not lose the ability to use it because another laboratory has announced something better.
The bill still has to find a customer
This is where I think the frontier race has a difficult question to answer: will enough people pay enough for the results to support the cost of staying ahead?
There are already paying customers. Microsoft reported more than 30 million paid Microsoft 365 Copilot seats in July 2026. That is the company’s disclosure, and it does not tell us Copilot’s standalone profit. It does make it impossible to argue that nobody is paying for AI. [5]
The question is whether paying demand will grow fast enough, at prices that cover today’s service and the next round of development.
We should be precise about the bill. Data-centre investment serves training, inference and other computing workloads; spending plans are not money already spent. Adding every large infrastructure announcement together does not give us a reliable figure for the cost of training AI.
Nor can we look at a subscription price, subtract the cost of generating answers and declare the whole company profitable. There are researchers, engineers, support teams, facilities and other costs to pay for. A service can bring in more than it costs to serve its users while the business as a whole still needs financing.
I do not need to predict anyone’s bankruptcy to take that problem seriously. The return on the next enormous commitment is uncertain. Whoever finances it is taking a risk that the person buying a useful answer does not have to take in the same form.
The customer is waiting for something useful
Suppose a small business wants its product catalogue translated properly. The model’s international ranking is interesting. Whether a customer can understand the product, its dimensions and how to order it is more immediately important.
A person who understands the language and the business can use AI to prepare the translation, check it, correct it and test it with readers. They may earn money for delivering work the customer values. They have not trained a frontier model. Their contribution still matters.
If the underlying model becomes cheaper, or a better alternative becomes available, that can improve their economics. But only if the arrangement lets them change tools without losing the work, and only if the result remains reliable.
Inference has costs: computing, memory, electricity and, when the system gets things wrong, repeated attempts and human checking. Even the amount of “thinking” is not a simple guide to the final bill. ARC Prize’s evaluations show that a better configuration can use more reasoning yet lower the total cost by reaching a solution with fewer actions. What matters is the cost of completing the task reliably. [6]
There are also customers to find, systems to connect and promises to keep. Competition can push down the price of the service just as it pushes down the price of the model.
People can build valuable businesses on capability they did not have to finance from scratch. They still have to do the difficult work of making it useful and earning enough to cover their own costs.
The people outside the map
The authors say that below a certain threshold of energy, capital and computing power, a country is “not in the game at all”. I understand that as a warning about frontier competition. I find it inadequate as an account of what everyone else can do. [1]
Consider a study of 5,172 customer-support agents, most working outside the United States, mainly in the Philippines. With an AI assistant, they resolved 15 per cent more issues per hour on average. Less-skilled and less-experienced workers improved by 30 per cent. The assistant offered suggestions; the workers could edit or reject them. [7]
This was one company and one kind of work. It shows that useful expertise can reach people far from the laboratory that developed the model. It does not tell us that those workers became economically independent.
There is a national version of that opportunity, too. AI Singapore’s SEA-LION programme adapts models for Southeast Asian languages and contexts. Its September 2026 collaboration with NVIDIA illustrates both the reliance on an international supplier and the regional capability being built around it. [8]
The authors themselves recognise that open models can spread and be adapted in ways their producers do not fully control. That possibility deserves more weight in how we think about the rest of the world. Dependence and useful local capability can develop together. The practical task is to understand which dependencies are dangerous and which choices can reduce them.
What does the person get to keep?
An empire can make some of the people within its reach more productive. Better output alone does not defeat the authors’ argument.
The customer-support study did not have compensation data. Its results cannot honestly be retold as a 30 per cent pay rise for beginners. The employer could keep much of the benefit, or turn improved performance into a higher target next month.
A separate Danish working paper found average effects on earnings and recorded hours close to zero through the end of 2024, despite reported benefits and changes in tasks. It is an early finding in a particular labour market, not a verdict on everyone’s future. It is a useful warning against assuming that access automatically becomes prosperity. [9]
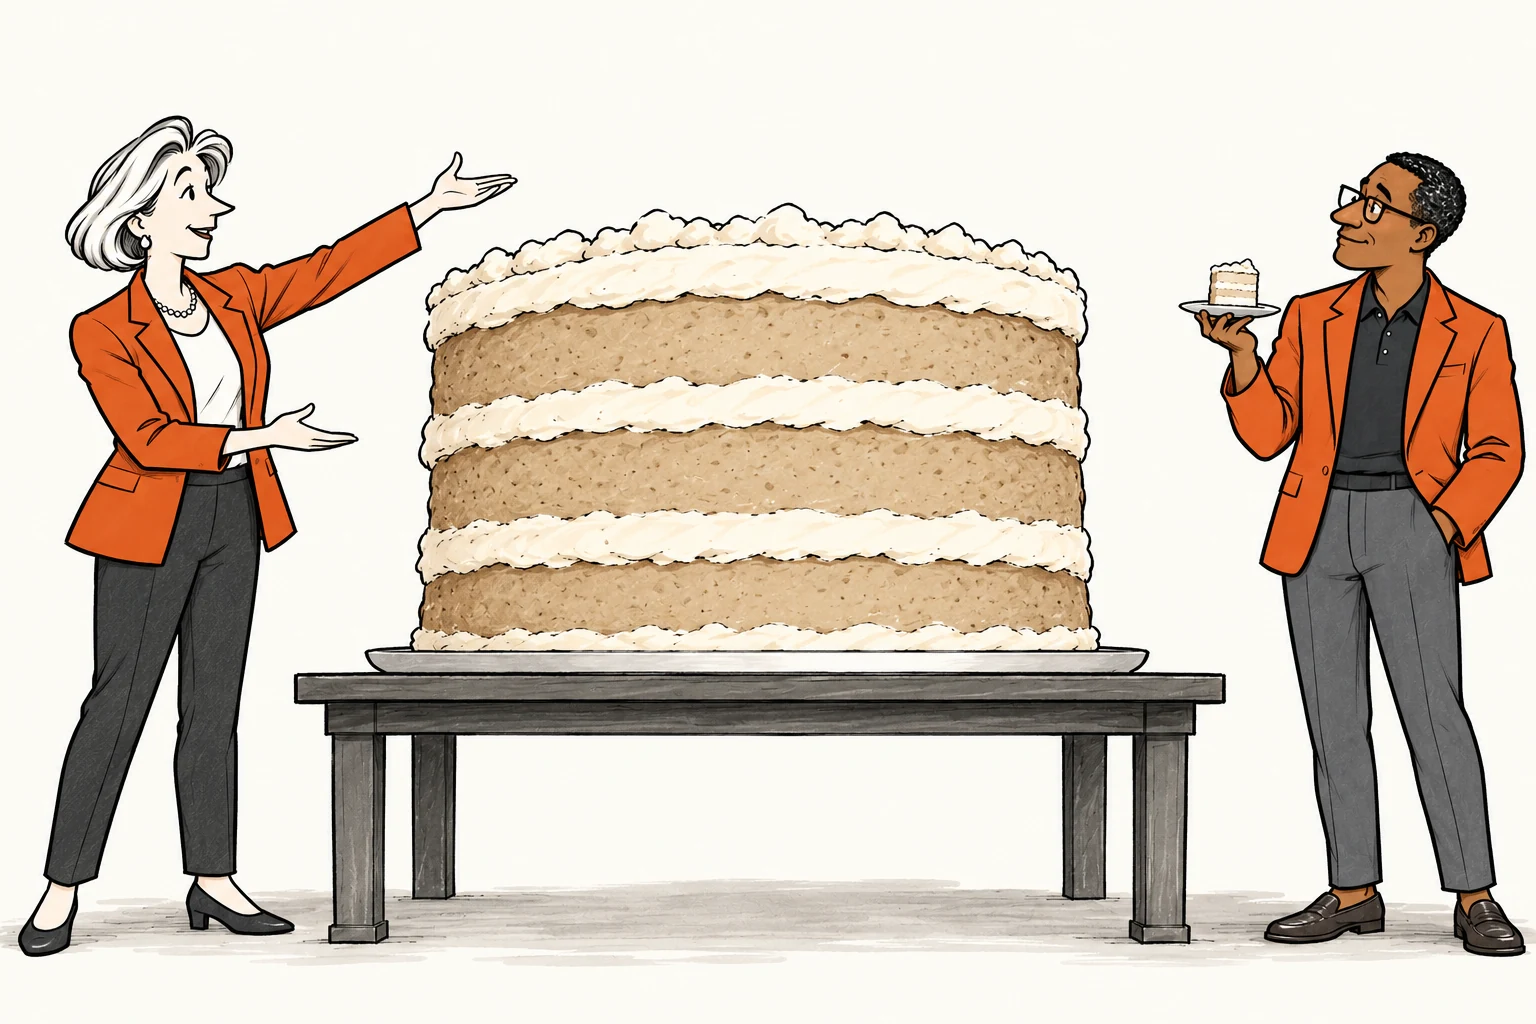
For me, amplifying human potential has to include what someone gets to keep. Knowledge they can use again. The ability to question an answer. More choice about the work they do. A fair share of the value they help create.
That gives us plenty to work on without waiting to own a frontier laboratory. Teach people to check results and develop knowledge of the work. Build services around actual local needs. Make it possible to move between suppliers. Give workers a say in how productivity gains affect their jobs and pay.
None of this removes the power held by the largest technology companies or the governments behind them. It gives us specific ways to contest that power and make the benefits reach further.
I want to know whether a student, a small business owner or a worker with fewer advantages can do something they could not do before, and whether doing it leaves them better off. I am not prepared to call them outside the game because they do not own the machine.